Instead of mining deep embeddings or gradients, SSR asks two explicit questions about every sample: what knowledge does it teach, and how is it delivered?
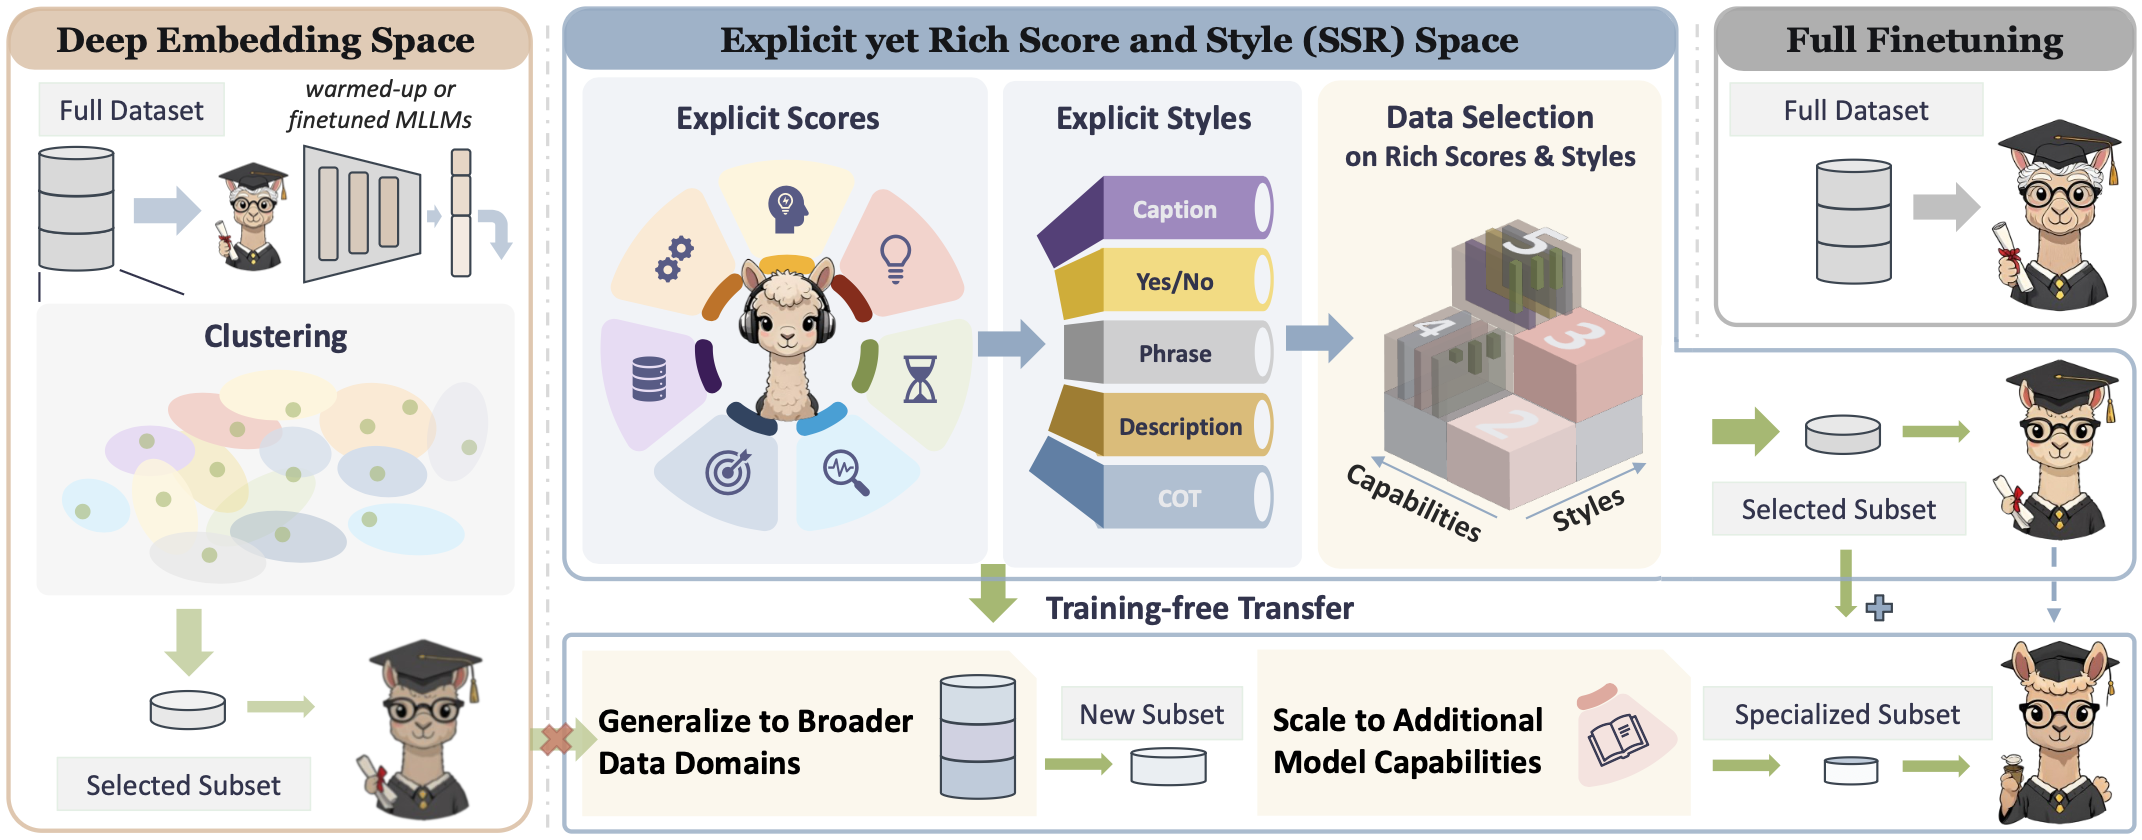
Each sample gets a 0–5 score on 14 interpretable vision-language capabilities, from spatial reasoning to STEM and OCR.
Each sample is tagged with its interaction style (multi-choice, captioning, chain-of-thought, …), a proxy for structural diversity.
Selection covers the capability–style grid with a simple round-robin, backed by a (1−1/e) coverage guarantee and EF1 fairness across cells.
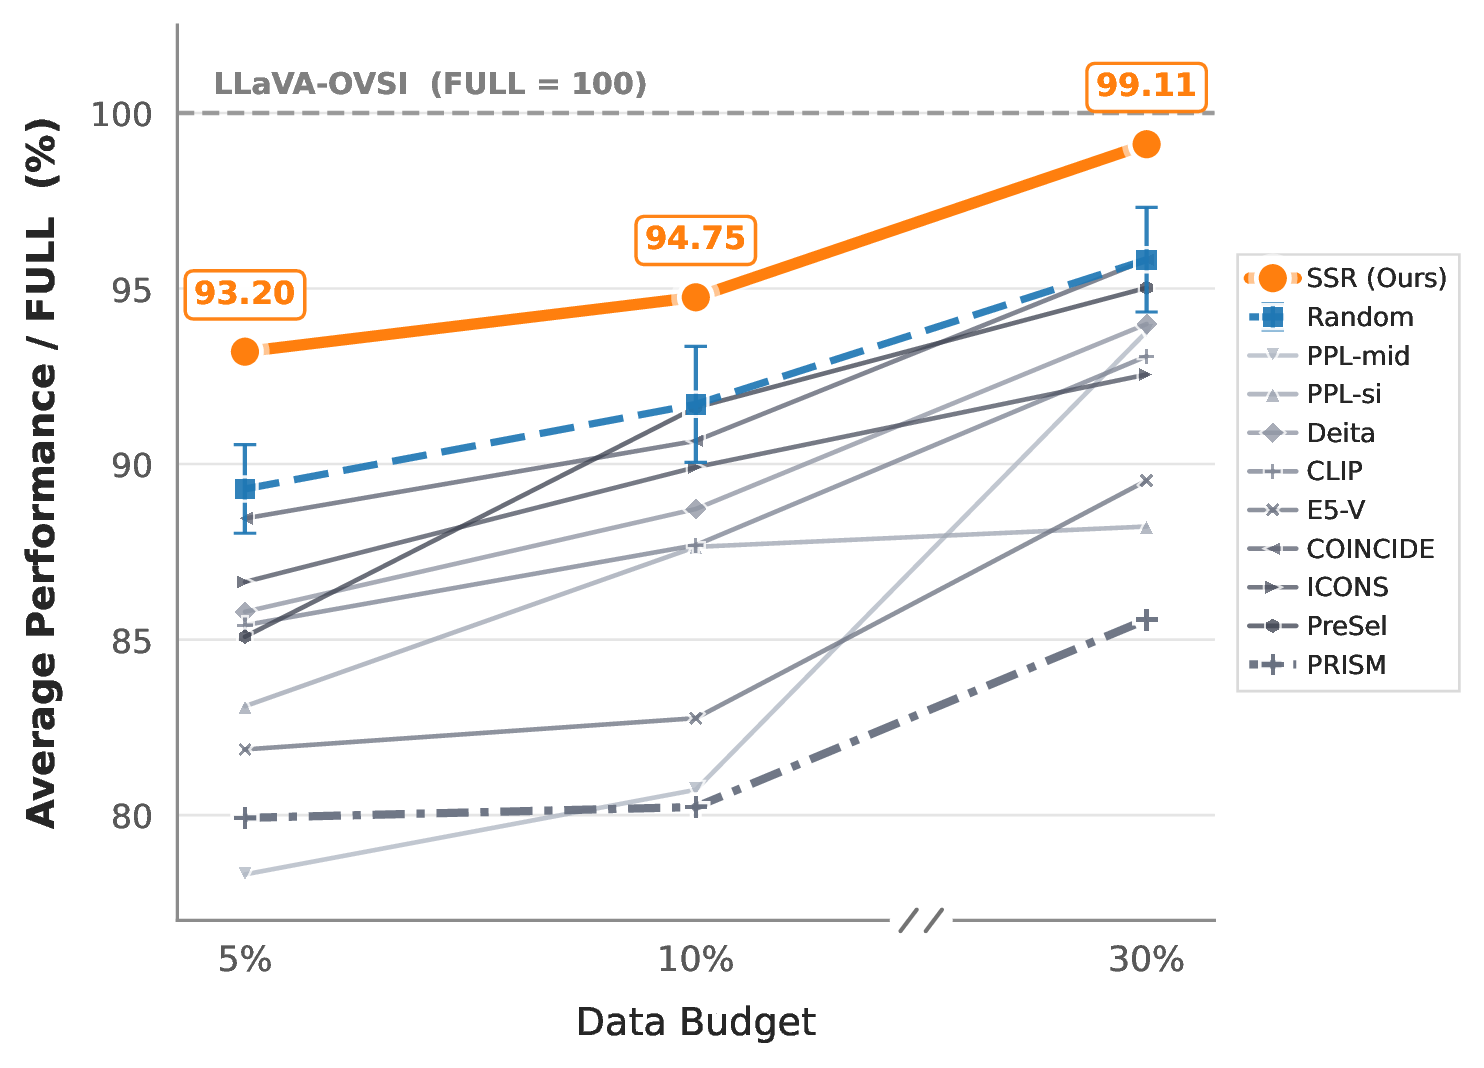
Selecting from the 2.6M LLaVA-OneVision pool, SSR has the best average at every budget and is the only one of 11 methods that reliably beats random sampling across benchmarks.
| MMBenchen-v1.1 | MMStar | MMMU | MMVet | BLINK | MMT-Bench | MME | AI2D | ScienceQA | MathVistamini | >Rand | /FULL | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Budget: 5% | ||||||||||||
| Random | 73.74 | 47.98 | 43.70 | 42.34 | 50.61 | 58.87 | 2004.50 | 73.07 | 81.52 | 45.47 | - | 89.29 |
| PPL-mid | 67.34 | 45.27 | 38.98 | 30.18 | 45.27 | 54.33 | 1887.71 | 66.74 | 74.76 | 31.40 | 0/10 | 78.31 |
| PPL-si | 71.98 | 44.67 | 38.48 | 35.14 | 54.10 | 57.98 | 1856.79 | 67.84 | 78.24 | 36.50 | 1/10 | 83.10 |
| Deitatop-k | 72.91 | 47.47 | 41.28 | 40.23 | 52.59 | 56.57 | 1956.50 | 70.76 | 79.57 | 36.10 | 1/10 | 85.79 |
| CLIP | 74.23 | 47.27 | 40.08 | 35.73 | 52.96 | 56.73 | 1902.65 | 73.61 | 78.63 | 39.80 | 3/10 | 85.41 |
| E5-V | 70.90 | 43.00 | 38.78 | 38.44 | 49.94 | 54.65 | 1810.47 | 66.58 | 77.54 | 37.40 | 0/10 | 81.87 |
| COINCIDE | 72.76 | 48.33 | 43.17 | 45.60 | 49.43 | 57.53 | 1852.66 | 73.15 | 79.62 | 45.40 | 3/10 | 88.45 |
| ICONS | 66.72 | 52.20 | 41.18 | 38.03 | 47.92 | 55.96 | 1811.13 | 76.20 | 83.64 | 46.90 | 4/10 | 86.64 |
| PreSel | 72.68 | 48.33 | 40.96 | 35.18 | 52.21 | 55.68 | 1954.35 | 69.01 | 79.38 | 40.70 | 2/10 | 85.08 |
| PRISM | 65.56 | 44.07 | 41.07 | 33.49 | 45.90 | 51.84 | 1807.73 | 65.54 | 76.60 | 40.30 | 0/10 | 79.92 |
| SSR (ours) | 77.79 | 53.33 | 43.27 | 43.53 | 51.83 | 59.16 | 1938.68 | 77.66 | 88.45 | 52.00 | 8/10 | 93.20 |
| Budget: 10% | ||||||||||||
| Random | 74.57 | 51.57 | 44.72 | 42.91 | 52.59 | 58.99 | 2033.28 | 74.42 | 84.33 | 47.80 | - | 91.70 |
| PPL-mid | 63.54 | 46.87 | 39.08 | 36.93 | 45.90 | 54.30 | 1831.03 | 67.23 | 73.87 | 39.50 | 0/10 | 80.72 |
| PPL-si | 74.69 | 49.80 | 41.28 | 40.60 | 53.09 | 57.95 | 1841.11 | 75.16 | 80.71 | 40.40 | 3/10 | 87.64 |
| Deitatop-k | 75.39 | 48.80 | 43.77 | 42.25 | 54.48 | 57.40 | 1996.34 | 71.60 | 78.33 | 40.80 | 2/10 | 88.72 |
| CLIP | 75.23 | 49.87 | 40.38 | 37.16 | 53.59 | 59.35 | 1921.04 | 76.62 | 80.07 | 41.00 | 4/10 | 87.69 |
| E5-V | 70.51 | 45.13 | 38.78 | 39.59 | 50.57 | 55.10 | 1787.94 | 68.94 | 77.54 | 37.20 | 0/10 | 82.76 |
| COINCIDE | 75.23 | 49.73 | 44.77 | 42.52 | 50.69 | 58.71 | 2027.58 | 74.77 | 82.05 | 47.00 | 3/10 | 90.66 |
| ICONS | 71.67 | 53.33 | 44.17 | 40.46 | 49.18 | 57.40 | 1789.60 | 76.65 | 85.23 | 51.10 | 4/10 | 89.91 |
| PreSel | 76.93 | 53.87 | 42.82 | 33.94 | 55.23 | 57.28 | 1904.98 | 79.44 | 92.86 | 50.40 | 6/10 | 91.61 |
| PRISM | 64.63 | 45.47 | 41.31 | 30.78 | 45.65 | 53.21 | 1849.71 | 66.13 | 76.20 | 42.10 | 0/10 | 80.23 |
| SSR (ours) | 77.32 | 53.27 | 45.06 | 42.98 | 54.10 | 59.61 | 2045.00 | 78.76 | 89.94 | 52.40 | 10/10 | 94.75 |
| Budget: 30% | ||||||||||||
| Random | 78.25 | 54.60 | 44.40 | 46.10 | 55.23 | 59.61 | 2092.60 | 78.28 | 88.32 | 52.57 | - | 95.82 |
| PPL-mid | 73.99 | 54.93 | 43.97 | 41.01 | 53.09 | 58.78 | 2036.54 | 77.20 | 87.01 | 56.40 | 2/10 | 93.77 |
| PPL-si | 72.52 | 48.33 | 42.57 | 43.62 | 51.83 | 55.07 | 1976.46 | 76.55 | 78.48 | 42.20 | 0/10 | 88.22 |
| Deitatop-k | 76.93 | 54.13 | 43.67 | 44.04 | 55.11 | 59.66 | 2042.63 | 79.50 | 83.54 | 50.30 | 2/10 | 93.99 |
| CLIP | 74.30 | 53.80 | 43.07 | 45.87 | 51.95 | 59.16 | 2039.14 | 80.02 | 83.99 | 48.80 | 1/10 | 93.07 |
| E5-V | 74.30 | 46.07 | 43.27 | 47.80 | 50.32 | 57.85 | 1955.13 | 74.45 | 81.61 | 43.70 | 1/10 | 89.53 |
| COINCIDE | 78.02 | 55.47 | 45.66 | 46.24 | 52.84 | 59.80 | 2047.37 | 79.73 | 84.33 | 55.10 | 6/10 | 95.82 |
| ICONS | 71.90 | 53.40 | 43.87 | 42.25 | 50.32 | 59.23 | 1985.64 | 78.21 | 86.76 | 54.10 | 1/10 | 92.55 |
| PreSel | 76.86 | 57.20 | 41.89 | 36.93 | 59.14 | 58.91 | 1971.60 | 81.61 | 93.75 | 55.20 | 5/10 | 95.02 |
| PRISM | 64.32 | 49.60 | 41.77 | 40.60 | 46.66 | 54.01 | 1898.22 | 70.43 | 81.26 | 47.40 | 0/10 | 85.57 |
| SSR (ours) | 79.57 | 57.53 | 44.87 | 48.49 | 56.24 | 59.83 | 2132.93 | 81.25 | 92.46 | 57.40 | 10/10 | 99.11 |
| FULL | ||||||||||||
| LLaVA-OVSI | 80.57 | 59.40 | 45.16 | 47.16 | 56.87 | 60.73 | 2117.56 | 81.87 | 92.76 | 59.60 | - | 100 |
Best result in bold; underlined if above random sampling. >Rand counts benchmarks where a method beats random; /FULL is average performance relative to training on the full pool.
The SSR profile describes the sample itself, not any model's latents, so selectors and selections carry over to new pools and architectures unchanged.
Selectors trained on 12-source ShareGPT4V (Vicuna + CLIP) pick data directly from the 91-source LLaVA-OVSI pool.
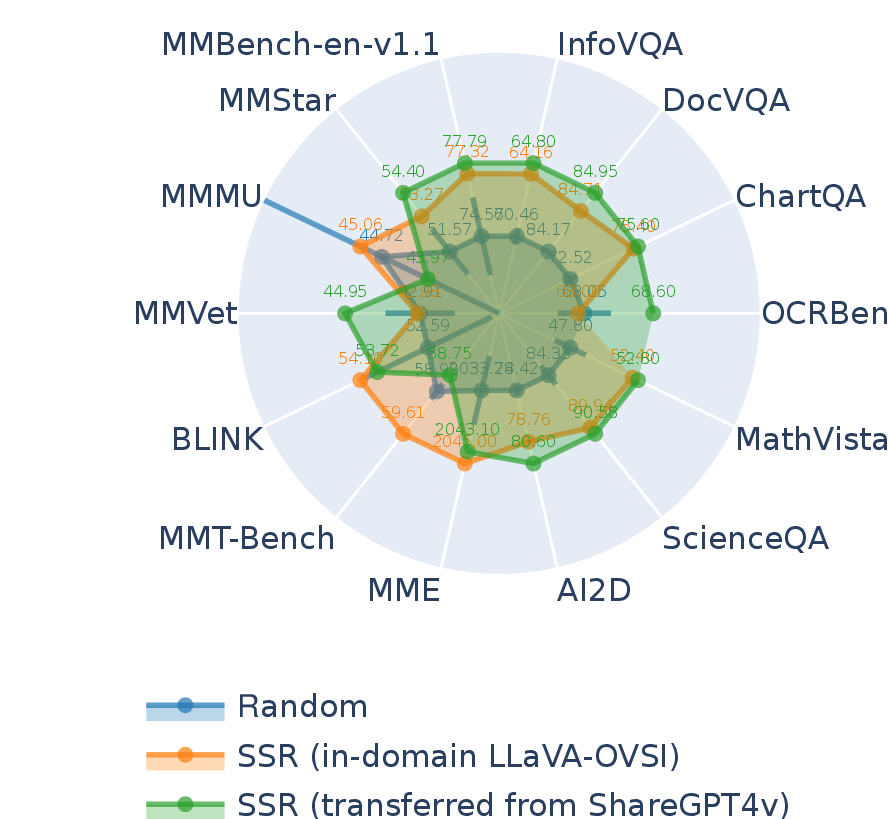
The 5% subset chosen with 7B selectors still wins when training a 14× smaller 0.5B model.
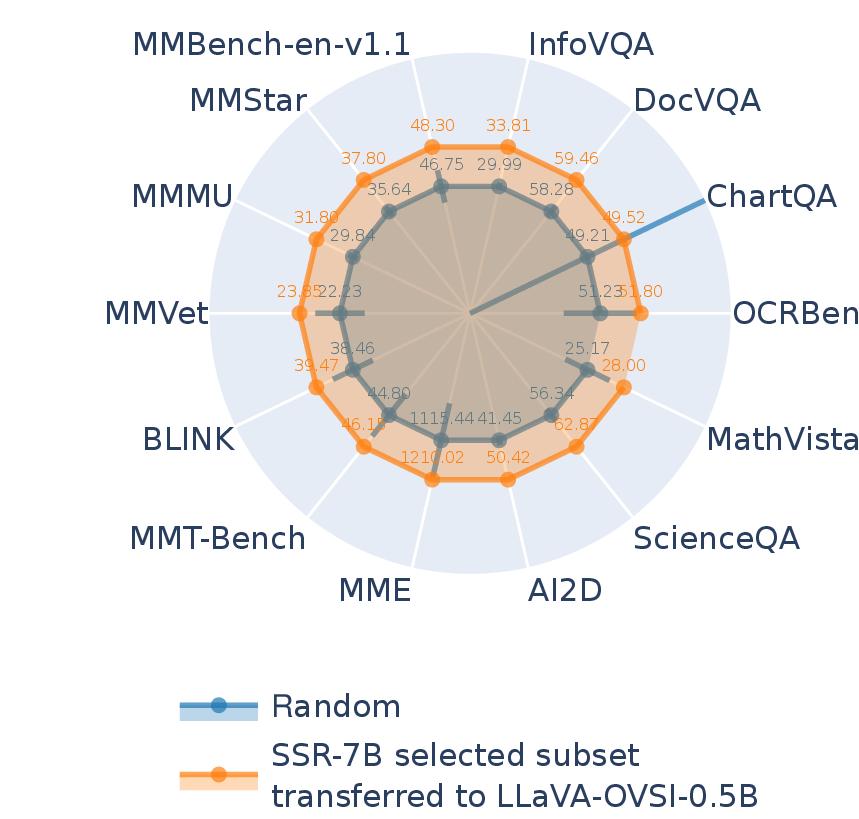
Zero-shot on the unseen Cambrian-7M pool, training Cambrian-1-8B (Llama-3 + four vision encoders). No re-annotation, no fine-tuning.
| /FULL (%) | 5% | 10% | 30% |
|---|---|---|---|
| Random | 90.54 | 93.57 | 97.85 |
| SSR | 92.40 | 94.35 | 98.19 |
The gains come from the richness of the profile, not from a lucky criterion set or an expensive annotator.
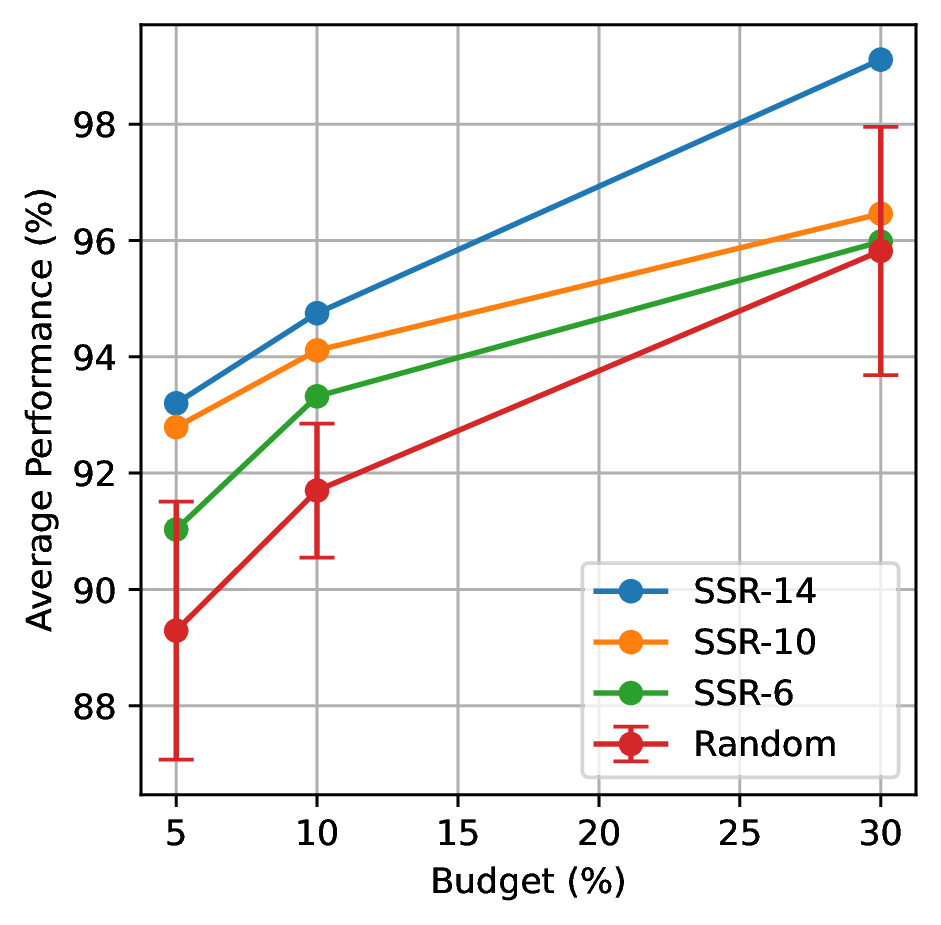
Randomly dropping capabilities (14 → 10 → 6) lowers performance gradually, yet every reduced set still clearly beats random sampling.
Our main setting distills GPT-4o labels on 15% of the pool. Simply prompting the open-weight Qwen2-VL-7B, with no training at all, already beats every prior method at every budget.
| /FULL (%) | 5% | 10% | 30% |
|---|---|---|---|
| Best prior method | 88.45 | 91.61 | 95.82 |
| SSR, prompting Qwen2-VL | 91.37 | 94.59 | 97.91 |
| SSR, distilled from GPT-4o | 93.20 | 94.75 | 99.11 |
@inproceedings{lyu2026ssr,
  title={An Embarrassingly Simple Data Selection Strategy for Million-Scale Multi-Modal Instruction-Tuning},
  author={Lyu, Mengyao and Li, Yan and Zhong, Huasong and Chen, Hui and Han, Jungong and Ding, Guiguang and Yang, Zhenheng},
  booktitle={Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing},
  year={2026}
}